
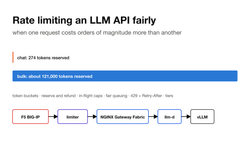
Rate limiting an LLM API fairly when one request costs orders of magnitude more than another: tokens, fair queuing, vLLM, llm-d and an F5 BIG-IP edge
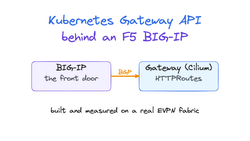
How do you rate limit a public LLM API fairly when requests range from a few tokens to a 128K context? Token buckets with reserve and refund, in-flight caps, fair queuing by tokens, 429 with Retry-After, and an F5 BIG-IP edge, on Kubernetes with NGINX Gateway Fabric, llm-d and vLLM.