Inference-Aware Load Balancing for LLMs (part 2): the model server on CPU, vLLM, the KV cache and a calibrated simulator
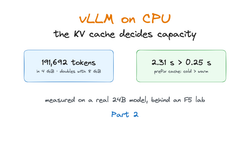
Inside vLLM with a real 24B model on a CPU node: the KV cache formula checked against the server's log and doubled by one setting, thread binding measured, prefix caching cold and warm, continuous batching read live from /metrics, and a simulator timed from the real model.