Inference-Aware Load Balancing for LLMs (part 1): from connections to tokens, what changes when the backend is an LLM
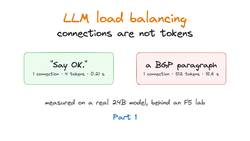
Why connection-based load balancing breaks for language models: tokens, streamed answers, prefill and decode, TTFT and TPOT, a reasoning model thinking before it answers, batching and Little's law, all measured on a real 24B model behind an F5 lab.