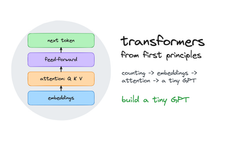
Transformers from first principles: build a tiny GPT, from counting letters to mixture of experts
How a language model turns next-token guessing into full answers, built up from a model that only counts letters: embeddings and gradient descent, attention worked by hand, the transformer block, tokenization, the KV cache, quantization, long context and mixture of experts.